

Message passing lifts small-model Sudoku score to 72 %
Junfan Zhu’s COLM roundup says persistent model threads reduced context needs and outperformed GPT-5 Pro without tools on the puzzle benchmark.
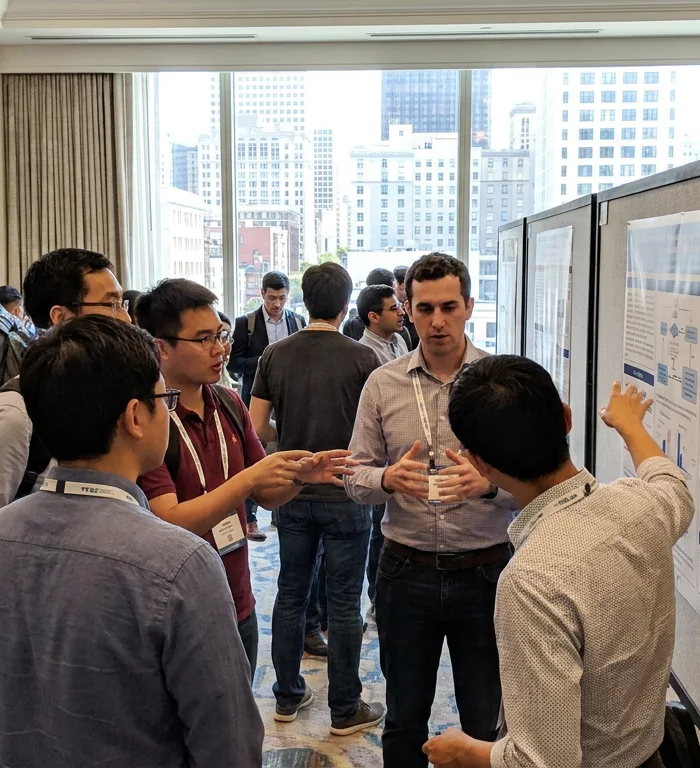
Carnegie Mellon researchers’ message-passing language-model poster at COLM 2026 showed a fine-tuned Qwen3-0.6B solving 72% of 25×25 Sudoku puzzles, according to an Oct. 12 X post by Junfan Zhu.
The result matters because Zhu said GPT-5 Pro without tools solved 20% on the same benchmark, making the poster a pointed example of architectural design outperforming model scale in a constrained reasoning task.
Zhu’s post described the CMU work as the centerpiece among 10 COLM posters focused on orchestration, adaptation and evaluation methods. The conference ran Oct. 6-9 at Hilton Union Square in San Francisco, according to the post.
The mechanism is message passing: separate persistent language-model threads handle subproblems and exchange text only with selected neighboring threads. Zhu quoted the project page as saying, “The protocol is learned, not hard-coded.”
In the Sudoku setup, Zhu said one worker was assigned to each cell, with 625 workers in a 25×25 grid. Each worker communicated with 64 row, column and box neighbors, implying an N/k ratio of about 9.8 in the post’s summary of the paper’s context-scaling argument.
The broader claim is efficiency. Zhu wrote that the largest single-thread context for serial and fork-join approaches scaled with exponents of about 1.78 to 1.85 against cell count, while the message-passing language-model approach scaled at 1.09.
The same roundup highlighted other COLM posters. SuperCoder was described as raising Qwen2.5-Coder-7B from a 61.4% pass rate and 1.10× speed versus gcc -O3 to a 95.0% pass rate and 1.46× speed. Zhu said Claude Opus 4, the fastest zero-shot model in that comparison, reached 51.5% and 1.43×.
Several posters targeted cheaper reasoning or better evaluation rather than bigger models. HyperThink used a hypernetwork to write a per-question bias update of about 0.015% of Qwen3-0.6B’s weights, while ORCA was described as saving 47.5% of reasoning steps in-distribution.
The limits are material. Zhu’s account is an X post summarizing posters and papers; the supplied material does not provide the underlying papers in full. It also notes caveats for the CMU theory, including upper-bound claims, an assumed local-processing condition and an initial-prompt cost not captured by the main formula.
Zhu said frontier-model comparisons used 20 puzzles per size through a batch API and were “not intended as a direct head-to-head evaluation.” For gaming and interactive-agent developers, the work is best read as a research signal, not evidence of a deployed product.
Source: X post by Junfan Zhu, Oct. 12, 2026
More stories
- Robotics at Amazon tests balance between speed and safety
- Gears E-Day No. 2 player-count claim sparks debate
- DualQuant may lower LLM memory use by 2.61x
- Loops AI raises $3.5 million seed round with a16z Speedrun
- Nvidia China share falls to 34% as Huawei gains
- God of War uses Avatar tech in 2 games as film ties deepen
- Anthropic cuts web access after AI testing incidents
- EA brings AFC Richmond Women to EA Sports FC 27
Latest news
- UK spy chief says Iran, Russia escalate campaigns
- Officials Report 11 Missing After Ships Hit Off Bulgaria
- Sweden's 176-seat left bloc stalls in government talks
- Lille Explores Legal Action Against LFP After Defender Tiago Santos Suffers Major Knee Injury
- Formula One Secures 10-Year Rwanda Grand Prix Deal
- Russia outreach tests Trump's divided base, Mead argues
- Compass Lexecon gets 2 leaders in FTI North America revamp
- AEye revenue grows ninefold as loss hits $10 million