ELMO1/DOCK2 preprint tests open-data AI drug discovery
A bioRxiv preprint outlines an open-data AI workflow targeting ELMO1/DOCK2, but its economic impact depends on peer review and replication.
Edward Mullen ·
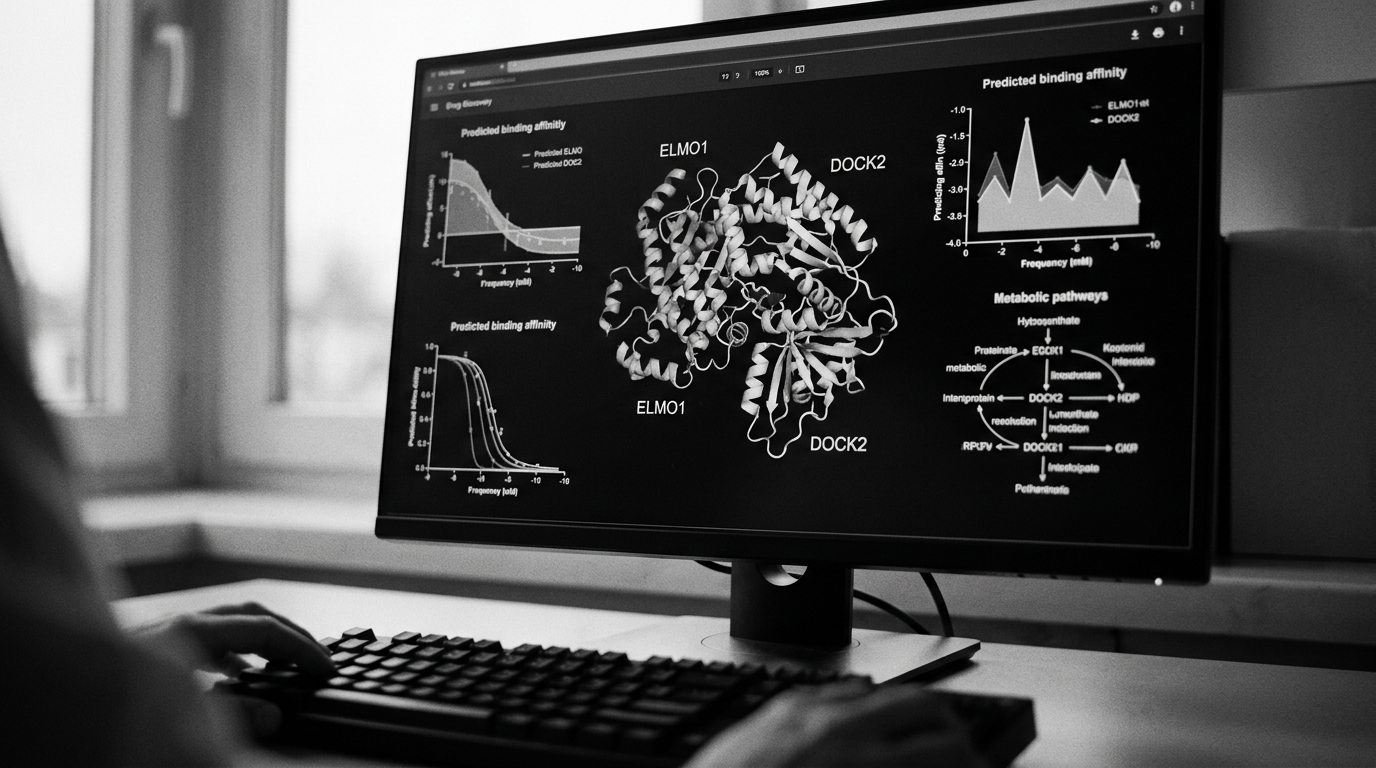
A recent bioRxiv preprint describes an AI-led computational workflow aimed at the ELMO1/DOCK2 complex, built using publicly available structural biology data and open tools. The work challenges the long-held assumption that meaningful drug-discovery advances must be anchored in proprietary datasets and closed research environments.
The preprint’s core claim is not a clinical breakthrough, but a demonstration of process: a structured, reproducible-style pipeline that could speed the earliest phase of small-molecule discovery for a protein–protein interaction (PPI). The authors argue that open structural models combined with molecular dynamics can help surface candidate compounds without relying exclusively on in-house medicinal chemistry playbooks or licensed datasets.
Open-access pipelines and the early-hit cost debate
In the framing laid out by the preprint In the framing laid out by the preprint, the economic signal sits at the “early-hit” stage—identifying plausible starting points that might later be optimized. If candidate generation can be done by reusing open structures, open code, and repeatable protocols, the marginal cost of producing initial hits could fall, according to the paper’s logic. That would imply a shift in what creates defensibility in early discovery: away from keeping data inaccessible and toward building capabilities around shared scientific infrastructure and compute execution. The material stops short of claiming that open workflows automatically replace proprietary approaches, but it presents a pathway that reduces dependence on exclusivity as the primary input. Preprint limits: reproducibility and real-world validation The packet also highlights the central constraint: this is a preprint and has not undergone peer review. As presented, the claims depend on whether the workflow can reproduce results across laboratories, datasets, and modeling environments—conditions the paper itself does not establish.
A key uncertainty is transferability
A key uncertainty is transferability.
If the pipeline performs reliably only under tightly controlled settings or for a narrow class of targets, the broader margin impact would be smaller than the most optimistic interpretation suggests. Another open question is benchmarking, because the preprint’s metrics are not yet positioned against industry-grade validation pipelines.
Who could benefit if robustness is confirmed
Assuming the method proves robust, the packet argues that more academic and biotech teams could participate in early discovery without new licensing deals for closed datasets or locked workflows. In that scenario, open-access AI models and public structure databases become standard inputs, potentially reducing cost-per-hit and shortening cycle times for early-stage programs.
The document also flags a counterweight: regulatory and validation costs. If regulators require additional demonstration of predictive reliability for computation-led candidates, the potential margin upside could be limited even if early hit-finding becomes cheaper.
Signals to watch in coming quarters
The packet identifies three practical indicators: whether large pharmaceutical companies disclose rising spending on proprietary data assets and compute infrastructure relative to external, open resources; whether startups using public structural data and open-source AI progress candidates into preclinical stages; and whether regulatory bodies introduce new requirements tied to validation practices for computation-led discovery.
No researchers are on the record in the provided material, and no proven outcomes are claimed. The central idea remains conditional on independent replication, cross-lab reproducibility, and real-world pharmacology results.
Implications
Country Impact: The material does not describe a country-specific policy change or national program. Any geographic impact depends on whether independent laboratories in different jurisdictions can replicate the open workflow using public data and tools.
Industry Impact: If validated, the approach could reduce reliance on proprietary datasets in early hit identification and widen participation among academic and biotech groups. The preprint status and the need for reproducibility and benchmarking remain key constraints on how quickly such workflows could be adopted.
Market Impact: The packet suggests a potential repricing of the earliest discovery stage if open data and open tools lower marginal costs for generating starting compounds. However, it also notes that regulatory and validation demands could limit margin gains even if computational screening becomes more accessible.